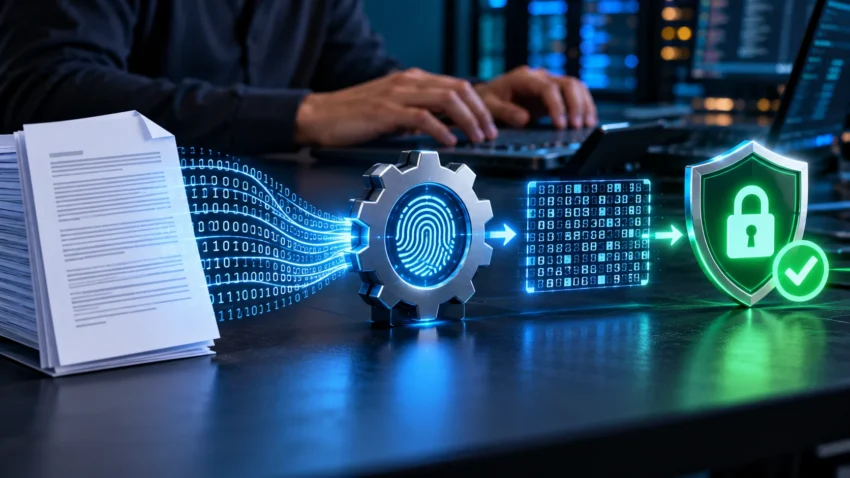
Data integrity is an important part of cybersecurity because organizations need to ensure that information remains accurate, complete, and unchanged during storage, transmission, and processing. Whether businesses manage customer records, financial transactions, or confidential documents, even a small unauthorized modification can create serious problems. Hash functions help address this challenge by generating unique-looking digital fingerprints that make changes to information easier to detect.
Understanding how a hash function contributes to data integrity is essential for cybersecurity professionals, software developers, IT specialists, and anyone learning about information security. Hashing helps verify whether files, messages, and other digital information have changed since their original state. However, hashing alone does not prevent modifications or prove who created the data. This guide explains how cryptographic hash functions work, their role in data integrity, common applications, security benefits, and important limitations.
What Is a Hash Function in Cybersecurity?
A hash function is a mathematical algorithm that converts input data into a fixed-length output called a hash value or hash digest. The input can be a short message, a document, a software file, or another collection of digital information. Cryptographic hash functions are designed so that even small input changes usually produce substantially different outputs. This property makes hashing useful for identifying modifications.
For example, a cybersecurity system can calculate a hash value for a document before it is transmitted. The receiving system can calculate another hash using the same algorithm after receiving the file. If the two values match, the document has likely remained unchanged. This process provides a practical method for checking data integrity.
Hash functions are widely used in cybersecurity, software development, digital signatures, and file verification. They operate without requiring the original data to be encrypted. However, not every hashing algorithm provides adequate cryptographic security. Modern applications should use algorithms that offer appropriate collision resistance and other necessary security properties.
What Is Data Integrity?
Data integrity refers to the accuracy, completeness, consistency, and trustworthiness of information throughout its lifecycle. It means that data has not been modified, deleted, corrupted, or altered in an unauthorized or unintended way. Maintaining integrity is important for organizations that rely on accurate records and dependable digital systems. Even small changes can affect business decisions and system operations.
In cybersecurity, data integrity is one of the three main principles of the CIA triad. The other principles are confidentiality and availability. Confidentiality focuses on preventing unauthorized access, while availability ensures that authorized users can access information when needed. Integrity focuses on preserving trustworthy information and identifying improper changes.
Organizations maintain data integrity through several security controls, including access management, validation, backups, audit logs, and cryptographic techniques. Hash functions are especially valuable because they help detect whether information has changed. They provide a practical way to compare data across different moments or locations. However, complete integrity protection requires more than hashing alone.
How Does a Hash Function Contribute to Data Integrity?
A hash function contributes to data integrity by generating a compact digital fingerprint of information. When data is first created or verified, a cryptographic hashing algorithm produces a hash value based on its contents. This value can later be compared with a newly calculated hash. If the values differ, the data has changed or a processing error has occurred.
The process works because secure cryptographic hash functions are highly sensitive to changes in input data. Modifying even one character or bit generally produces a substantially different digest. This makes unexpected changes easier to recognize without manually examining the entire file. Hash comparison is therefore useful for checking documents, software packages, database records, and transmitted messages.
However, hashing does not physically prevent someone from editing information. It only helps reveal changes when the expected hash is trustworthy. If an attacker can modify both the data and the reference hash, ordinary comparison may fail to identify tampering. For stronger protection against deliberate attacks, systems often combine hashing with digital signatures or message authentication codes.
How Does the Hashing Process Work?
The hashing process begins when a system provides data to a hashing algorithm. The algorithm performs mathematical operations that transform the input into a fixed-size digest. For example, SHA-256 produces a 256-bit hash value regardless of whether the input is a short sentence or a large document. The same input produces the same output when processed using the same algorithm.
After generating the original hash, the system stores or transmits it through an appropriate mechanism. Later, the data can be processed again using the same hashing algorithm. The resulting digest is compared with the original value. Matching hashes provide strong evidence that the information has not changed, assuming a secure algorithm and trustworthy reference value.
If the hashes differ, the system knows that the inputs were not identical. The difference might result from accidental corruption, an authorized edit, or malicious modification. Hashing cannot explain why the data changed or identify who made the modification. Additional security logs, access controls, and investigation procedures are needed to determine the cause.
What Is a Hash Value or Hash Digest?
A hash value is the output generated when data passes through a hash function. It acts as a compact representation of the original input. Cryptographic digests are commonly displayed as hexadecimal strings containing numbers and letters. Their length depends on the algorithm rather than the size of the original information.
For example, SHA-256 produces a 256-bit digest, commonly displayed using 64 hexadecimal characters. A large software installation file and a short text message can both produce digests of this length. However, their hash values will generally be different because their contents differ. This fixed-length property supports efficient comparison.
A hash digest is sometimes described as a digital fingerprint, but the comparison is not perfect. Because the number of possible inputs exceeds the number of available hash values, collisions are mathematically unavoidable. Strong algorithms are designed to make finding useful collisions computationally impractical. This distinction is important when evaluating hashing security.
Key Properties of Cryptographic Hash Functions
Cryptographic hash functions have several properties that make them useful for protecting data integrity. One important property is determinism, which means identical inputs produce identical hash values. This allows systems to verify information consistently. Without deterministic output, reliable comparison would not be possible.
Another important property is preimage resistance. Given a secure hash value, it should be computationally infeasible to discover an input that produces that particular digest. Second-preimage resistance makes it difficult to find a different input matching the hash of a known message. These properties support the security of cryptographic applications.
Collision resistance is particularly important for detecting deliberate data substitution. It should be computationally difficult to find any two different inputs that produce the same hash. Secure algorithms also demonstrate an avalanche effect, where small input differences produce substantially different outputs. Together, these properties make cryptographic hashing valuable for integrity verification.
How Hash Functions Detect Unauthorized Changes
Hash functions detect unauthorized changes by comparing a current digest with a previously established reference value. When information is created or approved, a trusted system can calculate and protect its original hash. Later, the same data can be hashed again to verify whether its contents remain identical. Any mismatch signals that the information has changed.
For example, an organization may maintain an approved software file and record its SHA-256 digest. If the file is modified after approval, its newly calculated hash will almost certainly differ. Security monitoring software can detect this mismatch and generate an alert. Administrators can then investigate whether the modification was expected or suspicious.
This approach is commonly used in file integrity monitoring systems. Such systems may check critical configuration files, application components, and other important resources. However, hash mismatches alone cannot distinguish malicious tampering from legitimate updates. Organizations need change management records and other evidence to interpret the results accurately.
Why Small Data Changes Produce Different Hashes
Secure cryptographic hash functions are designed to distribute the effects of input changes throughout their output. This behavior is commonly called the avalanche effect. Changing a single bit of input typically changes many bits of the resulting digest. Consequently, two similar documents can have very different hash values.
For example, changing one character in a file usually produces a different SHA-256 digest. The algorithm does not attempt to preserve visible similarities between the two inputs. Instead, it transforms the information through repeated mathematical operations. This makes small modifications easy to detect through hash comparison.
The avalanche effect improves change detection, but it does not independently guarantee every cryptographic security property. Collision resistance and preimage resistance remain separate requirements. A hashing algorithm must be evaluated as a complete design rather than judged only by how different its outputs appear. Modern standardized algorithms are generally preferred for security-sensitive applications.
Common Hashing Algorithms Used for Data Integrity
Several hashing algorithms have been developed for different computing and cybersecurity applications. Well-known examples include MD5, SHA-1, SHA-256, SHA-512, and the SHA-3 family. These algorithms differ in digest length, internal design, performance, and security properties. Choosing an appropriate algorithm is essential when integrity verification must resist deliberate manipulation.
MD5 produces a 128-bit digest, while SHA-1 produces a 160-bit digest. Both algorithms have known cryptographic weaknesses and should not be used for new collision-resistant security applications. SHA-256 and SHA-512 belong to the SHA-2 family and provide stronger security properties. SHA-3 offers another standardized family of cryptographic hash functions.
For many current applications, SHA-256 is a practical and widely supported option. However, the correct choice depends on system requirements and the security properties needed. Some specialized environments use alternative approved algorithms. Developers should follow current security standards instead of selecting an algorithm solely because it is familiar or fast.
SHA-256 and Its Role in Data Integrity
SHA-256 is a cryptographic hash function belonging to the Secure Hash Algorithm 2 family. It accepts input data and produces a fixed-length 256-bit digest. The algorithm is widely used for file verification, digital signatures, certificates, and other security applications. Its resistance to practical collision attacks makes it suitable for many integrity-checking purposes.
A software provider may publish a SHA-256 checksum alongside a downloadable installation file. Users can calculate the file’s digest after downloading it and compare the result with the published value. A mismatch indicates that the downloaded data differs from the expected file. This can reveal incomplete downloads, corruption, or unauthorized modification.
However, the published checksum must come from a trustworthy source. If an attacker controls both the download and the checksum displayed beside it, the comparison may provide false reassurance. Digitally signed releases offer stronger verification of authenticity. SHA-256 is therefore especially useful when integrated into a secure distribution and verification process.
How Hash Functions Protect File Integrity
File integrity verification is one of the most common applications of cryptographic hashing. A system calculates a digest for a file when its contents are known to be correct. The hash can then serve as a reference during future checks. If the file changes, the resulting digest will almost certainly differ.
This method is useful for software installation packages, system configuration files, backups, and important business documents. For example, administrators may periodically compare the hashes of critical application files against approved versions. Unexpected differences can reveal configuration drift or possible tampering. Automated monitoring tools can make these checks more efficient.
File hashing is also valuable during data transfer. Organizations can compare hashes before and after transferring large files between servers. Matching digests provide strong evidence that the content remained intact. However, authenticity still depends on the security of the reference hash and surrounding verification process.
How Hash Functions Support Secure Data Transmission
During data transmission, information may be exposed to accidental corruption or malicious interference. Cryptographic hashes can help detect changes between the original and received data. A sender may calculate a digest before transmission, while the receiver calculates another afterward. Comparing the two values helps determine whether the transmitted information remained unchanged.
However, sending a plain hash alongside data does not provide strong protection against an active attacker. Someone able to modify the message may also replace its hash with a matching value. This means ordinary hashing alone cannot authenticate the sender. Stronger communication systems use authenticated cryptographic mechanisms to address this weakness.
Message authentication codes and digital signatures provide additional protection by connecting integrity verification with authentication. They allow recipients to verify more than simple data consistency. Secure communication protocols often incorporate these mechanisms as part of a broader security design. Hash functions support the process but are not a complete secure transmission solution on their own.
Hash Functions and Digital Signatures
Digital signatures use cryptographic techniques to help verify message integrity and the authenticity of a signing key. In many signature schemes, a hash function first produces a digest of the message. The signing operation then uses that digest within a cryptographic signature process. This makes digital signatures practical for documents and other large data.
When a recipient verifies a digital signature, the system checks whether the signature corresponds to the message and the relevant public key. If the signed message has been modified, verification should fail under a secure implementation. This provides stronger evidence than comparing two unauthenticated hashes. The recipient can also associate the signature with the holder of the corresponding private key.
Digital signatures are widely used in software distribution, electronic documents, and secure communications. However, a valid signature does not automatically establish a person’s real-world identity without trustworthy key management. Certificates and other identity-verification processes may be necessary. Hash functions contribute to the cryptographic foundation that makes these systems possible.
What Is the Difference Between Hashing and Encryption?
Hashing and encryption serve different purposes in cybersecurity. Hashing converts information into a fixed-length digest that is not designed to be reversed into the original input. Encryption transforms information into protected ciphertext that authorized users can decrypt with the appropriate key. These technologies address different security objectives.
Encryption primarily supports confidentiality by preventing unauthorized parties from understanding protected information. Hashing is commonly used to support integrity verification by identifying changes in data. Some encryption methods also provide authentication and integrity through additional cryptographic mechanisms. Therefore, encryption and hashing can complement each other in secure systems.
For example, a company may encrypt a confidential file to protect its contents from unauthorized access. It may also use a cryptographic hash or digital signature to verify integrity. Each mechanism addresses a different risk. Understanding this distinction helps organizations select appropriate technologies for confidentiality, integrity, and authentication.
What Is the Difference Between Hashing and Checksums?
Checksums are values calculated from data to help detect changes or errors. They are frequently used in file transfers, storage systems, and communication protocols. Some checksum algorithms are designed primarily to detect accidental corruption rather than intentional attacks. They can be computationally efficient but may not provide strong cryptographic security.
Cryptographic hash functions are designed to resist specific forms of deliberate manipulation. Their collision resistance and other security properties make them useful in environments where attackers may attempt to alter information. Ordinary checksums generally do not provide the same protection. This difference matters when choosing an integrity-checking method.
For example, a simple checksum may help detect accidental transmission errors in a file. A SHA-256 digest provides stronger assurance against deliberately crafted substitutions when the reference value is trustworthy. However, even a cryptographic hash cannot authenticate data by itself. The appropriate method depends on the threats and requirements of the application.
How Hash Functions Support Database Integrity
Databases contain important information that businesses need to keep accurate and consistent. Hash functions can help verify whether selected records, files, or data structures have changed. A system may calculate digests for critical information and compare them with protected reference values. Unexpected mismatches can trigger further investigation.
Hashing can also support audit mechanisms that detect modifications in sequences of records. For example, a system may connect each record to the hash of a previous record. Changing an earlier entry would then affect the calculated values of later entries. This technique can make tampering more apparent when the chain is securely maintained.
However, hashing alone does not enforce database accuracy or prevent unauthorized updates. Databases also require access controls, transaction management, validation rules, backups, and monitoring. A malicious administrator with control over records and reference hashes may bypass simple verification. Strong integrity protection depends on several coordinated security measures.
Hash Functions in Blockchain Technology
Blockchain systems commonly use cryptographic hashes to connect blocks of transaction information. Each block typically contains a cryptographic reference to the previous block. This creates a chain in which changing an earlier block affects the validity of later references. Hashing therefore contributes to making historical modifications detectable.
Cryptographic hashes are also used in structures such as Merkle trees, which summarize collections of transactions. These structures allow systems to verify whether particular data belongs to a committed collection. They support efficient verification without requiring every participant to process every item in the same way. Their usefulness depends on correct cryptographic implementation.
However, blockchain integrity does not come from hashing alone. Consensus mechanisms, digital signatures, network rules, and other security controls also contribute. Hash chains can be recalculated if an attacker has sufficient control over the surrounding system. Understanding these dependencies prevents the mistaken belief that hashing automatically makes information impossible to change.
Advantages of Hash Functions for Data Integrity
One important advantage of cryptographic hashing is that it provides an efficient way to compare large amounts of information. A large file can be represented by a relatively small, fixed-length digest. Systems can compare these values rather than manually examining every component. This supports practical verification across many computing environments.
Another benefit is the sensitivity of secure cryptographic hashes to input changes. Even small modifications usually produce different digests, helping detect altered content. Hash functions are also deterministic, so identical inputs produce identical outputs. These characteristics make them useful for repeated verification and automated security monitoring.
Hashing is widely supported across operating systems, programming languages, and security tools. This availability makes integration relatively straightforward for many applications. However, the security benefits depend on algorithm selection, implementation quality, and trustworthy reference values. Organizations should consider these factors when developing integrity protection systems.
Limitations of Hash Functions in Cybersecurity
Although hash functions are valuable, they cannot prevent someone from modifying a file or message. Their primary role in integrity checking is detecting differences. If an attacker changes data and replaces the stored reference hash, ordinary comparison may not reveal the attack. This is why reference hashes must be protected or authenticated.
Another limitation involves hash collisions. Because hash functions map many possible inputs into a limited number of outputs, collisions are mathematically unavoidable. Secure algorithms make useful collisions extremely difficult to find. However, older algorithms such as MD5 and SHA-1 have demonstrated weaknesses that make them unsuitable for certain security applications.
Hashing also does not guarantee that the original data was correct or trustworthy. A file containing inaccurate information can still have a valid hash. The digest verifies consistency with a reference, not factual truth. Reliable data integrity therefore requires validation, access controls, trustworthy sources, and appropriate organizational procedures.
Best Practices for Using Hash Functions
Organizations should select modern cryptographic hash algorithms that meet current security requirements. SHA-256 and other appropriately standardized algorithms are commonly suitable for many integrity-checking applications. Legacy algorithms with known collision weaknesses should be avoided when collision resistance is required. Security standards should guide implementation choices.
Reference hashes should be stored or distributed through trustworthy mechanisms. Digital signatures, authenticated messages, and protected storage can help prevent unauthorized replacement of expected values. Regular verification may also be useful for critical files and configurations. Monitoring systems should distinguish expected updates from potentially suspicious changes.
Hashing should be combined with additional security controls rather than treated as a complete protection strategy. Access management, secure backups, audit logging, and data validation all contribute to maintaining trustworthy information. Organizations should also test their integrity-checking processes periodically. A layered approach provides stronger protection against accidental corruption and deliberate manipulation.
Conclusion
A hash function contributes to data integrity by generating a fixed-length digital digest that helps identify changes in information. When the same data is hashed again, the new value can be compared with a trusted reference. Matching values provide strong evidence that the content remains unchanged. This makes cryptographic hashing useful for files, databases, software downloads, and digital communications.
Modern cryptographic algorithms such as SHA-256 offer important security properties, including collision resistance and sensitivity to input changes. These characteristics support reliable integrity checking when implemented correctly. However, hashing alone cannot prevent modifications, verify a sender’s identity, or guarantee that information is accurate. Stronger protection often requires digital signatures, authentication mechanisms, and other security controls.
Understanding hashing is essential for maintaining secure and trustworthy digital systems. Organizations can use cryptographic hashes to detect unexpected changes and support broader cybersecurity processes. The effectiveness of these methods depends on choosing suitable algorithms and protecting reference values. When combined with proper security practices, hashing becomes a valuable tool for preserving data integrity.
Frequently Asked Questions (FAQs)
How does a hash function contribute to data integrity?
A hash function creates a fixed-length digest of data that can be compared with a trusted reference value. If the digests differ, the information has changed, helping detect corruption or unauthorized modification.
Can a hash function prevent data tampering?
No, a hash function does not stop someone from modifying data. It helps detect changes when the original hash is trustworthy. Digital signatures or message authentication codes provide additional protection against deliberate tampering.
Why is SHA-256 used for data integrity?
SHA-256 produces a 256-bit digest and offers strong cryptographic security properties. It is widely supported and commonly used to verify file integrity, software downloads, digital signatures, and other security-sensitive information.
What is the difference between hashing and encryption?
Hashing produces a fixed-length digest primarily used for verification and related purposes. Encryption protects information by transforming it into ciphertext that authorized users can decrypt using the appropriate cryptographic key.
Can two different files have the same hash value?
Yes, hash collisions are mathematically possible because the number of possible inputs exceeds the number of hash outputs. However, secure cryptographic algorithms make finding useful collisions computationally impractical.