Data is at the center of modern business decisions, scientific research, analytics, machine learning, and everyday digital services. However, raw data is rarely perfect when it first enters a database or spreadsheet. Duplicate records, missing values, inconsistent formats, spelling mistakes, outdated information, and incorrect entries can all reduce the value of otherwise useful datasets.
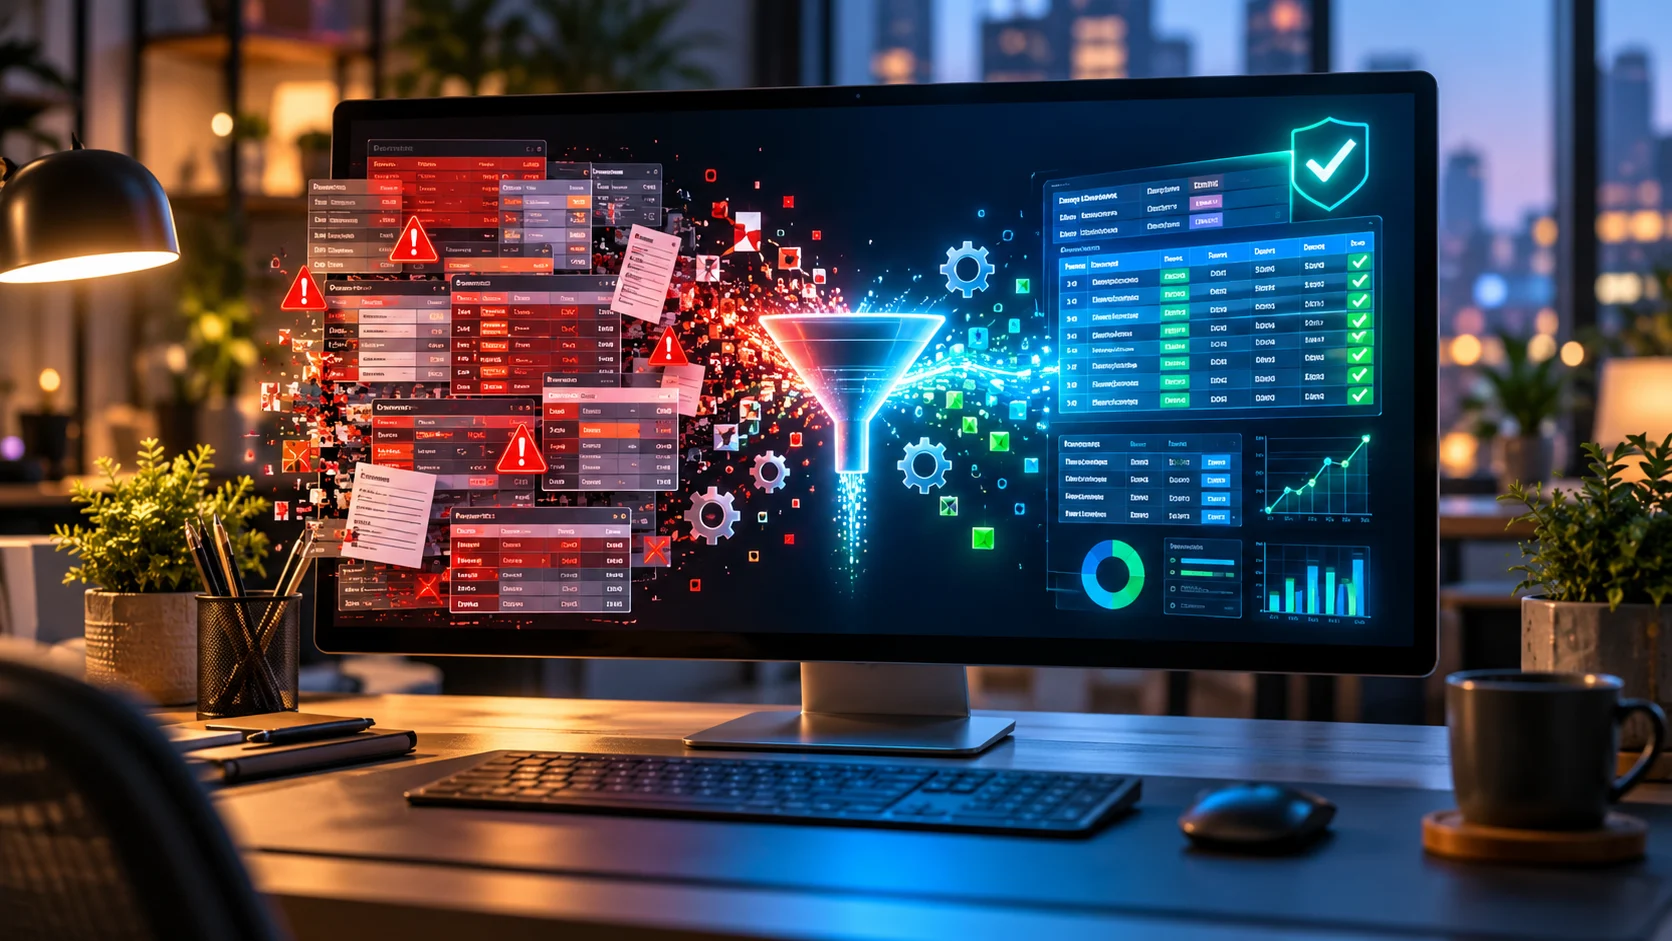
Data cleansing is the process of identifying and correcting these problems so information becomes more accurate, consistent, complete, and suitable for analysis. Organizations use data cleansing before generating reports, training artificial intelligence models, studying customers, conducting research, or making strategic decisions. Clean data helps users trust the conclusions they draw from the information available to them.
Understanding data quality has become increasingly important as organizations collect larger amounts of information from websites, applications, surveys, sensors, customer systems, and online platforms. Without proper cleaning, even advanced analytical tools can produce misleading outputs. A strong data cleansing process therefore provides the foundation required for reliable analysis, automation, and decision-making.
What Is Data Cleansing And Why Is It Necessary?
Data cleansing, also called data cleaning, involves finding inaccurate, incomplete, duplicated, irrelevant, or inconsistent information and correcting or removing it when appropriate. The goal is not simply to make a spreadsheet look organized. Instead, cleansing improves the quality of information so applications, analysts, researchers, and decision-makers can use it confidently.
When people ask What Is Data Cleansing And Why is It Necessary, the main reason is reliability. A company may have thousands of customer records, but inaccurate email addresses, duplicated profiles, and incorrectly formatted phone numbers can make the database far less valuable. Cleaning helps transform scattered information into a dataset that more accurately reflects reality.
Data cleansing also prevents small errors from becoming larger business problems. Incorrect information can affect financial forecasts, marketing campaigns, research findings, inventory planning, customer communications, and performance reports. By detecting issues before data is widely used, organizations can reduce unnecessary mistakes and improve confidence in their analytical results.
What Is Data Cleaning Process With Examples?
The data cleaning process usually begins with examining the dataset to understand its structure and identify obvious quality problems. Analysts may search for blank fields, repeated records, unusual values, inconsistent capitalization, incorrect dates, or information stored in different formats. These issues are then reviewed to determine whether they should be corrected, standardized, replaced, or removed.
Consider a customer database where one person appears as “John Smith,” “john smith,” and “J. Smith” with the same email address. A cleaning process may identify those records as duplicates and combine them into one accurate customer profile. Similarly, telephone numbers written in several formats can be standardized so every record follows the same structure.
Another example involves numerical data. Suppose a dataset records customer ages, but one record accidentally shows an age of 450 instead of 45. Validation rules can flag that value as an outlier for investigation. Understanding What is data cleaning process with examples makes it easier to see how ordinary errors can influence larger analytical results.
Why Is Data Cleansing Important Before Analyzing Data?
Anyone wondering What Is Data Cleansing And Why is It Important before analyzing data should consider how strongly results depend on input quality. Analytical software processes the information it receives, even when that information contains errors. If inaccurate values remain in the dataset, charts, averages, forecasts, correlations, and business conclusions can all become misleading.
Data cleaning improves analytical accuracy by removing unnecessary noise and correcting obvious inconsistencies. For example, duplicate transactions could make revenue appear higher than it actually is, while missing sales records could produce the opposite effect. Cleaning ensures calculations are based on information that more closely represents real activities and outcomes.
This explains What Is Data Cleansing And Why is It Important in data analysis. Analysts need consistent data structures before comparing categories, calculating performance, or identifying trends. Educational technology resources such as The Tech AI can help readers understand how accurate information supports modern analytics, artificial intelligence, automation, and other data-driven technologies.
What Is Data Cleaning in Research?
What is data cleaning in Research can be explained as the process of reviewing collected research information for mistakes, missing responses, inconsistent answers, coding problems, and unsuitable observations. Researchers often clean survey results, experiment records, interview coding, laboratory measurements, and observational datasets before beginning statistical analysis. This helps protect the accuracy of their findings.
Research datasets frequently contain incomplete information because participants may skip questions or provide unusual responses. Researchers must decide whether missing values should remain empty, be excluded from particular calculations, or be handled through an appropriate statistical method. The correct decision depends on the research design, methodology, dataset, and purpose of the study.
Cleaning also helps researchers identify data-entry mistakes and inconsistent coding. For example, one researcher might record gender categories numerically while another uses written labels, creating inconsistencies when datasets are combined. Standardizing these values ensures statistical software can interpret them correctly and helps researchers produce findings based on a more dependable dataset.
Data Cleaning in Data Science
Data cleaning in data Science is one of the most important steps in preparing information for exploration, modeling, visualization, and predictive analysis. Data scientists often receive information from several sources, including databases, APIs, spreadsheets, applications, and web platforms. Each source may structure information differently, creating inconsistencies that need correction before meaningful analysis begins.
Understanding What Is Data Cleansing And Why is It Important in data science becomes especially important when datasets contain millions of records. Even a relatively small percentage of inaccurate entries can distort calculations at scale. Data scientists therefore profile datasets, examine missing values, standardize categories, detect outliers, remove duplicates, and validate important fields before building analytical models.
Clean data also makes collaboration easier. When variables use predictable naming conventions, date formats, measurement units, and categories, other analysts can understand and reuse the dataset more efficiently. Good cleaning practices therefore support reproducibility, faster analysis, reliable modeling, and clearer communication between data scientists, engineers, researchers, and business stakeholders.
Data Cleaning in Machine Learning
Data cleaning in machine learning directly affects how effectively a model learns patterns from training information. Machine learning algorithms depend on historical examples to identify relationships and generate predictions. If those examples contain incorrect labels, duplicates, missing information, irrelevant variables, or inconsistent formats, the model may learn unreliable patterns and deliver weaker results.
Suppose an organization trains a model to identify fraudulent transactions, but many legitimate purchases are incorrectly labeled as fraud. The model may learn patterns based on those wrong labels and produce excessive false alerts. Cleaning training data helps reduce these problems by improving label accuracy, removing problematic records, and creating more consistent input variables.
Machine learning workflows may also require handling outliers, scaling numerical variables, converting categories into usable values, and addressing missing information. These preparation steps are closely connected with data cleaning because models generally perform better when input data is structured consistently. Better data does not guarantee a perfect model, but poor data can seriously limit one.
Difference Between Data Cleaning and Data Cleansing
The Difference between data cleaning and data cleansing is generally very small because the terms are commonly used interchangeably. Both describe processes used to identify and correct inaccurate, incomplete, duplicated, outdated, or inconsistent information. In many businesses, research teams, and data science environments, people use either term without intending a technical distinction.
Some professionals use “data cleansing” to describe broader quality improvement across databases, while “data cleaning” may refer more specifically to correcting individual dataset problems. However, this distinction is not universal. The exact meaning often depends on the organization, software platform, or data management framework being used rather than an industry-wide rule.
For practical purposes, users can treat cleaning and cleansing as closely related concepts focused on improving data quality. What matters most is establishing clear rules for identifying errors, documenting corrections, standardizing formats, and validating results. Consistent processes are more important than deciding which of the two terms should be used.
Common Data Problems That Need Cleaning
Duplicate records are among the most common data-quality issues. They may appear when information is entered more than once, multiple databases are merged, or customers use slightly different details across transactions. Duplicates can inflate counts, distort performance metrics, increase storage requirements, and create confusion when organizations attempt to build an accurate view of users or activities.
Missing and inconsistent values create additional challenges. One system might store a date as day-month-year while another uses month-day-year, creating problems when datasets are combined. Similarly, missing addresses, product codes, phone numbers, or survey responses can limit analysis because important variables are unavailable for comparisons, filtering, segmentation, or modeling.
Outdated and inaccurate information can be equally damaging. A customer may change an address, a business may update its contact information, or a product may receive a new category. Keeping old records without reviewing them can reduce database reliability, which is why periodic cleaning remains important even after an initial dataset has already been processed.
What Is Data Cleaning? Importance and Benefits
If someone asks, “What is data cleaning write down its importance and benefits,” accuracy should be the first benefit mentioned. Clean information provides a stronger foundation for decisions because managers, analysts, researchers, and automated systems can work with fewer obvious errors. Reliable datasets can improve reporting, forecasting, customer segmentation, research analysis, and operational planning.
Efficiency is another important benefit. Employees can waste significant time fixing repeated problems whenever they create reports or combine information from different sources. Establishing regular cleaning procedures reduces duplicated effort and allows teams to spend more time analyzing information rather than repeatedly correcting basic formatting, duplication, and accuracy problems.
Data cleaning can also support better customer experiences and resource management. Accurate contact information helps companies communicate successfully, while clean product and inventory records improve operational visibility. Large personal or organizational datasets should also be stored responsibly, and choosing reliable Best Cloud Storage solutions can support organized backups while data quality processes protect the usefulness of the information itself.
What Is the Purpose of a Data Cleansing Tool?
When asking What is the purpose of data cleansing tool, the main purpose is to automate or simplify repetitive data-quality tasks. A cleansing tool can scan large datasets for duplicates, missing fields, inconsistent formats, invalid values, and other patterns that would take much longer to identify manually. Automation becomes particularly valuable when organizations manage millions of records.
Many tools can standardize addresses, normalize capitalization, identify duplicate customers, validate information, and apply predefined transformation rules. For example, a tool may automatically convert several date formats into one consistent format before analysis. Some solutions also create reports showing which records were changed, allowing teams to review corrections and maintain greater transparency.
However, tools should not completely replace human judgment. Software can identify unusual values, but it may not always understand whether those values are genuine errors or legitimate exceptions. The strongest cleansing process therefore combines automation with appropriate business rules, validation procedures, documentation, and human review for uncertain or high-impact cases.
A Practical Data Cleaning Workflow
A reliable workflow begins by defining what good data should look like. Teams should identify required fields, valid formats, acceptable ranges, category structures, duplicate rules, and other quality expectations before making changes. Clear standards prevent different employees from cleaning information in conflicting ways and make future datasets easier to manage consistently.
The next stage involves profiling and correcting the dataset. Users can identify missing values, duplicates, spelling variations, unusual records, formatting differences, and invalid entries. Corrections should be made systematically rather than randomly, and teams should preserve an original copy whenever possible so changes can be reviewed or reversed if unexpected problems occur.
Finally, cleaned data should be validated again before being used. Analysts can run quality checks to confirm important fields are complete, duplicates have been addressed, formats are consistent, and values fall within reasonable ranges. Documenting these steps also creates a repeatable process that can be applied whenever new information enters the organization.
Best Practices for Maintaining Clean Data
Preventing errors is generally easier than correcting thousands of records later. Organizations can improve data quality by using dropdown selections, required fields, formatting rules, validation checks, and consistent naming standards when information is first collected. These controls reduce the number of unnecessary variations and mistakes entering databases, spreadsheets, applications, and customer systems.
Regular cleaning schedules are equally important because data quality can decline over time. Customer information changes, databases grow, new systems are connected, and employees may introduce inconsistent records. Monthly, quarterly, or automated quality reviews can identify emerging problems before they spread across reporting systems and become expensive or difficult to correct.
Teams should also establish ownership for data quality. When everyone assumes someone else will correct problems, inaccurate information can remain unnoticed for long periods. Assigning responsibility, documenting standards, monitoring quality metrics, and training employees in correct data-entry practices help create a culture where reliable information is treated as an ongoing business responsibility.
Conclusion
Data cleansing is the process of identifying and correcting problems that reduce the accuracy, consistency, completeness, or usefulness of information. It includes removing duplicates, standardizing formats, handling missing values, correcting errors, reviewing outliers, and validating records. These activities prepare data for research, analytics, machine learning, reporting, and everyday business operations.
Its importance continues to grow as organizations depend more heavily on automated systems and data-driven decisions. Poor-quality data can influence forecasts, customer communication, scientific findings, artificial intelligence models, and strategic planning. Cleaning information before analysis helps reduce these risks and gives users greater confidence in the results produced from their datasets.
The strongest approach combines prevention, regular monitoring, automated tools, clear standards, and human review. Data cleaning should not be viewed as a one-time task performed only when something goes wrong. Maintaining clean information over time creates a more reliable foundation for analysis, research, technology, and better decision-making.
FAQs
What is data cleansing in simple words?
Data cleansing means finding and correcting inaccurate, incomplete, duplicated, or inconsistent information in a dataset. The goal is to make data more reliable and suitable for analysis, reporting, research, or automated processing.
Why is data cleaning important before data analysis?
Data cleaning reduces errors that could distort calculations, charts, trends, and conclusions. Analysts can make more dependable decisions when duplicates, missing values, invalid records, and inconsistent formats are addressed before analysis begins.
What are the main steps in the data cleaning process?
Common steps include profiling the data, identifying errors, removing duplicates, handling missing values, standardizing formats, correcting invalid information, reviewing outliers, and validating the cleaned dataset before it is used.
How is data cleaning used in machine learning?
Machine learning teams clean training data to improve consistency, correct labels, manage missing values, remove problematic duplicates, and prepare variables. Better-quality training information generally allows models to learn more meaningful patterns.
Are data cleaning and data cleansing the same?
Yes, data cleaning and data cleansing are usually treated as interchangeable terms. Some organizations make minor distinctions between them, but both primarily refer to improving the accuracy, consistency, and usefulness of data.